AI Data Engineering Services
Accelerate every phase of your data engineering lifecycle from ingestion and schema mapping to pipeline testing and migration - using enterprise-ready AI accelerators that cut development cycles by 30-50%.
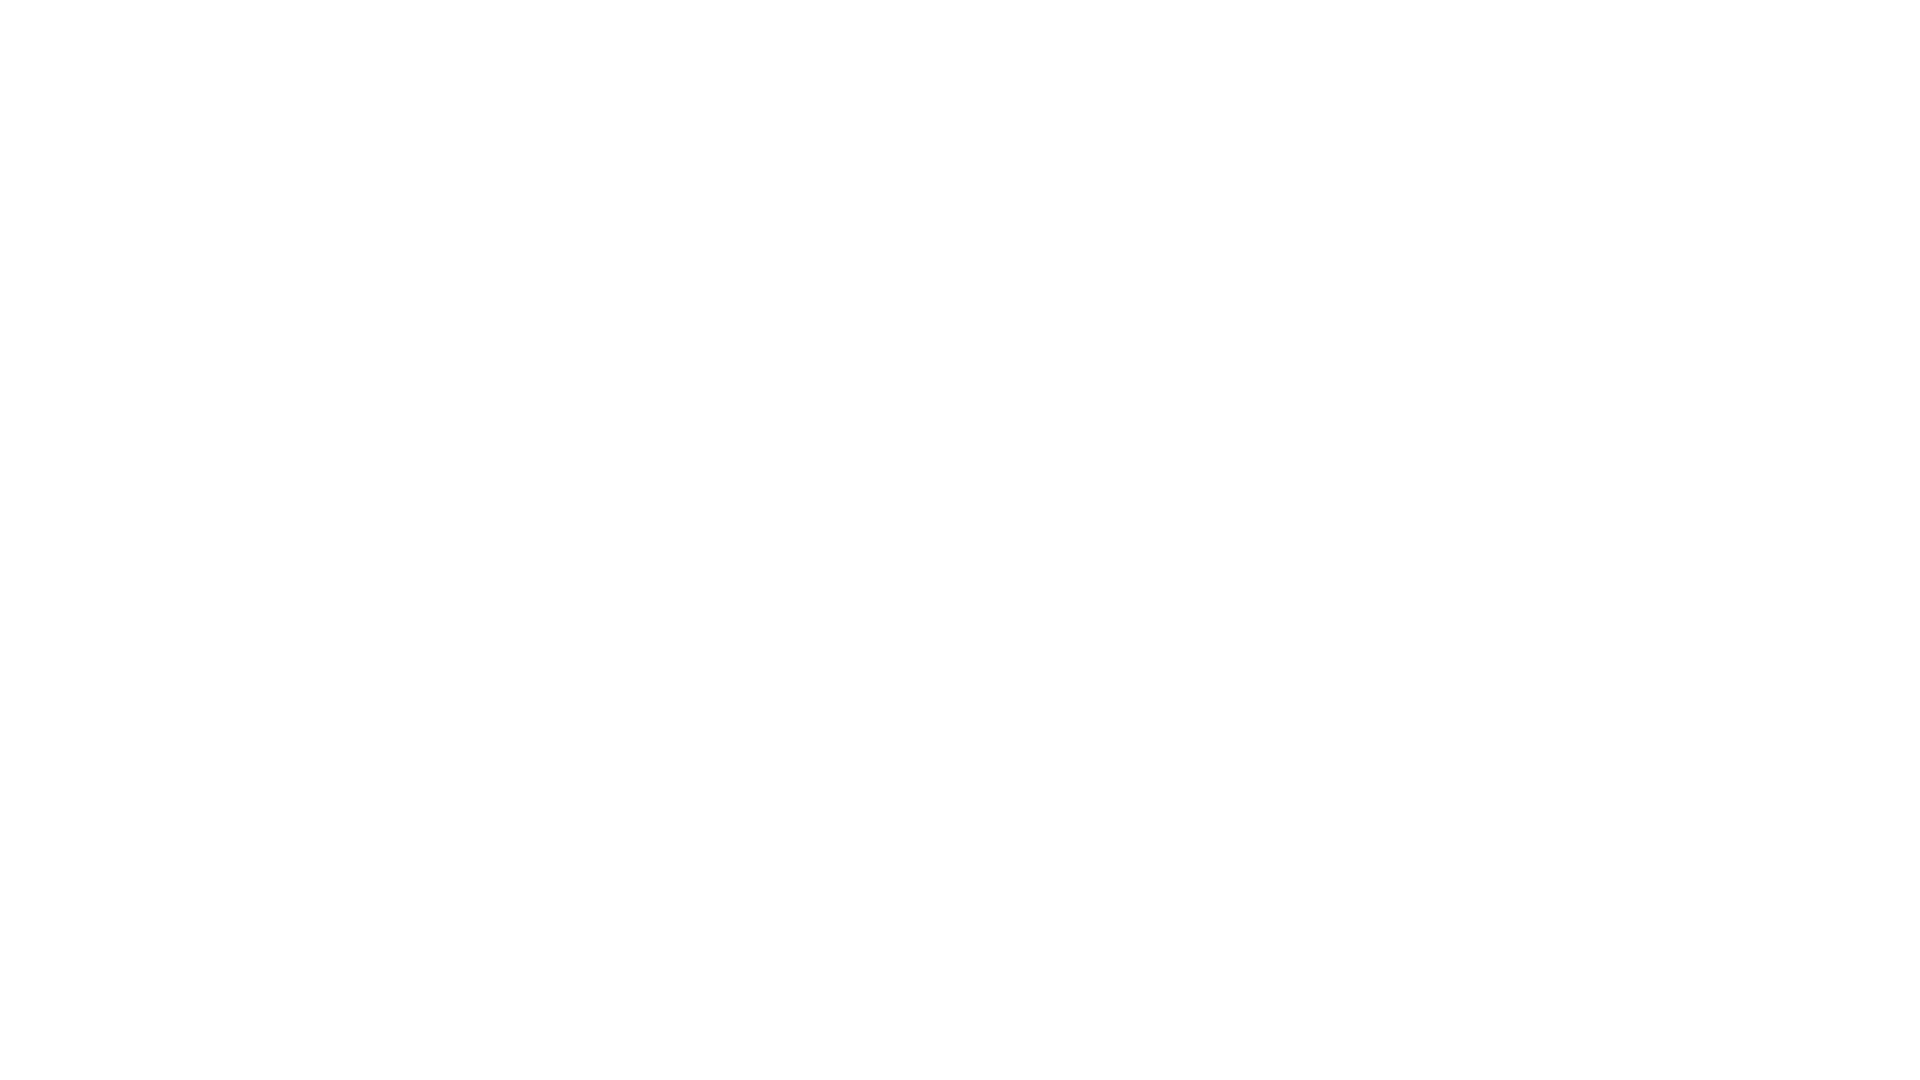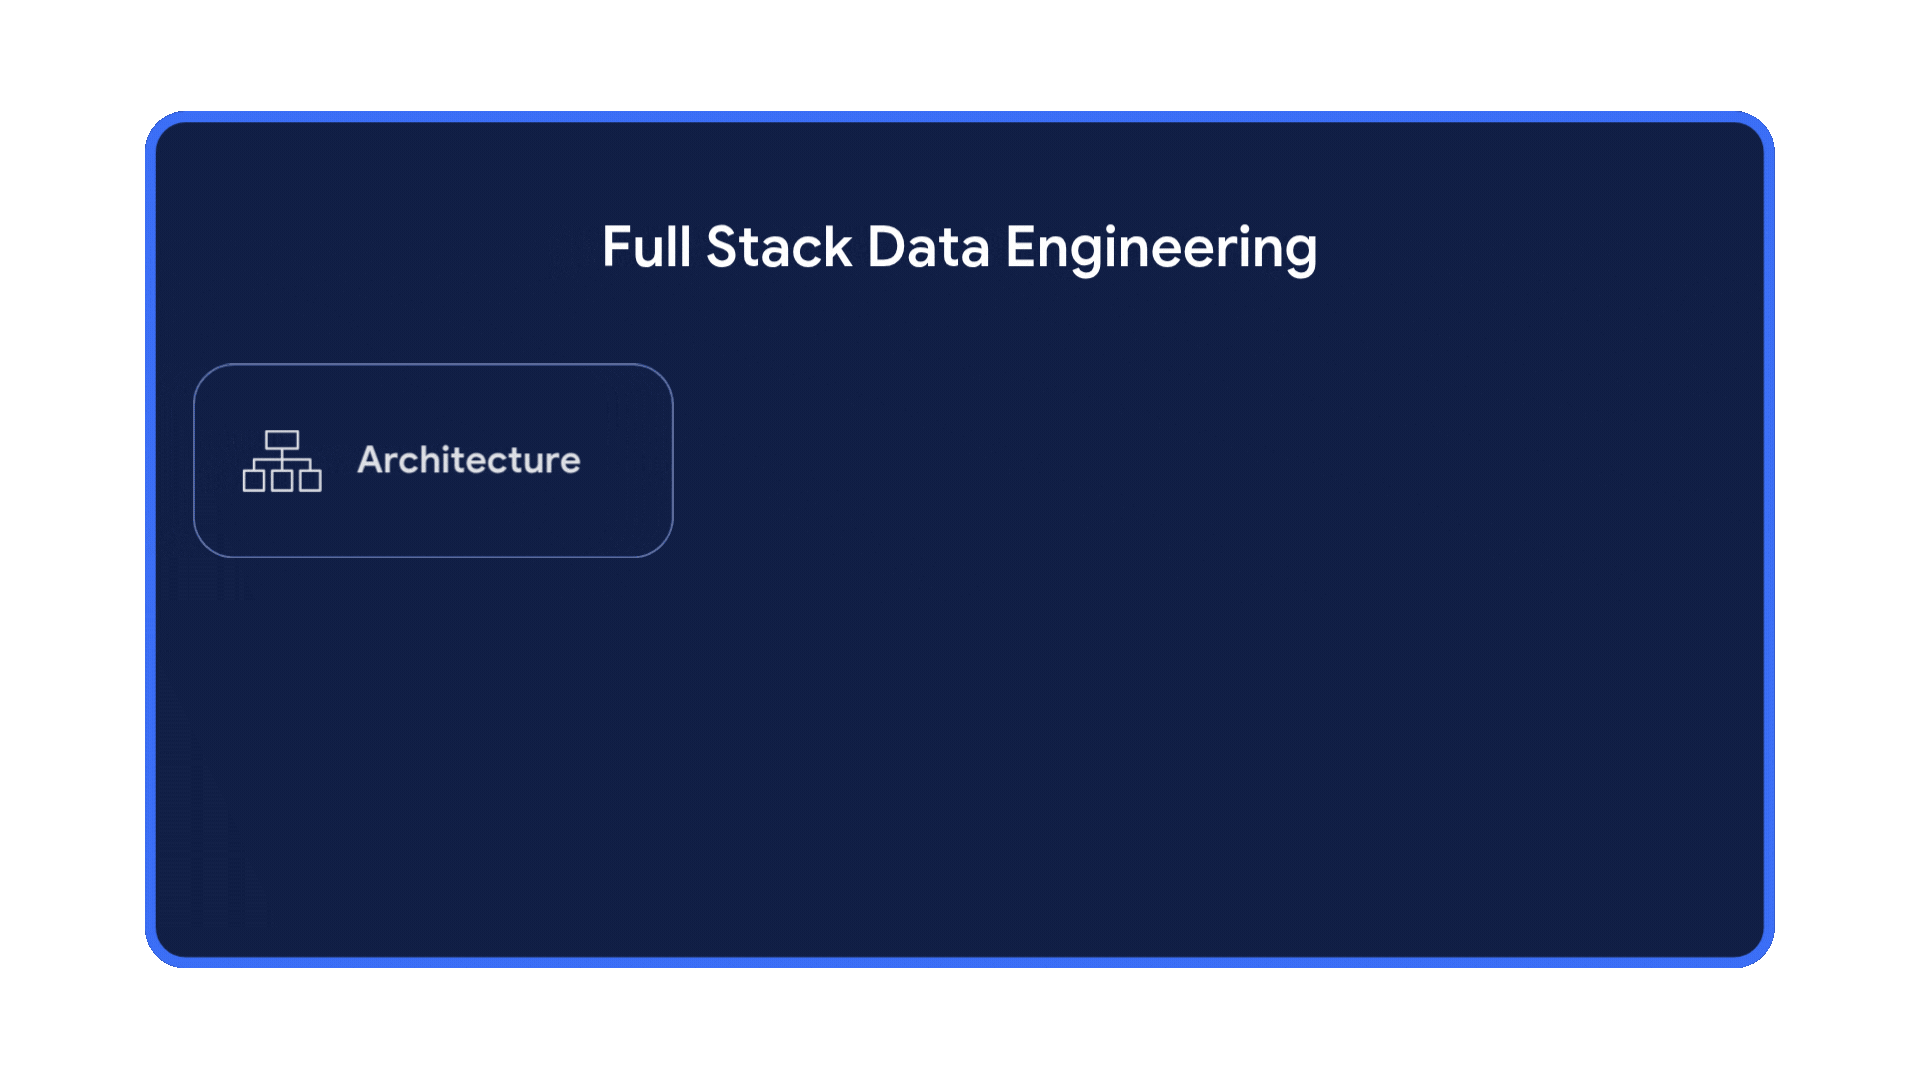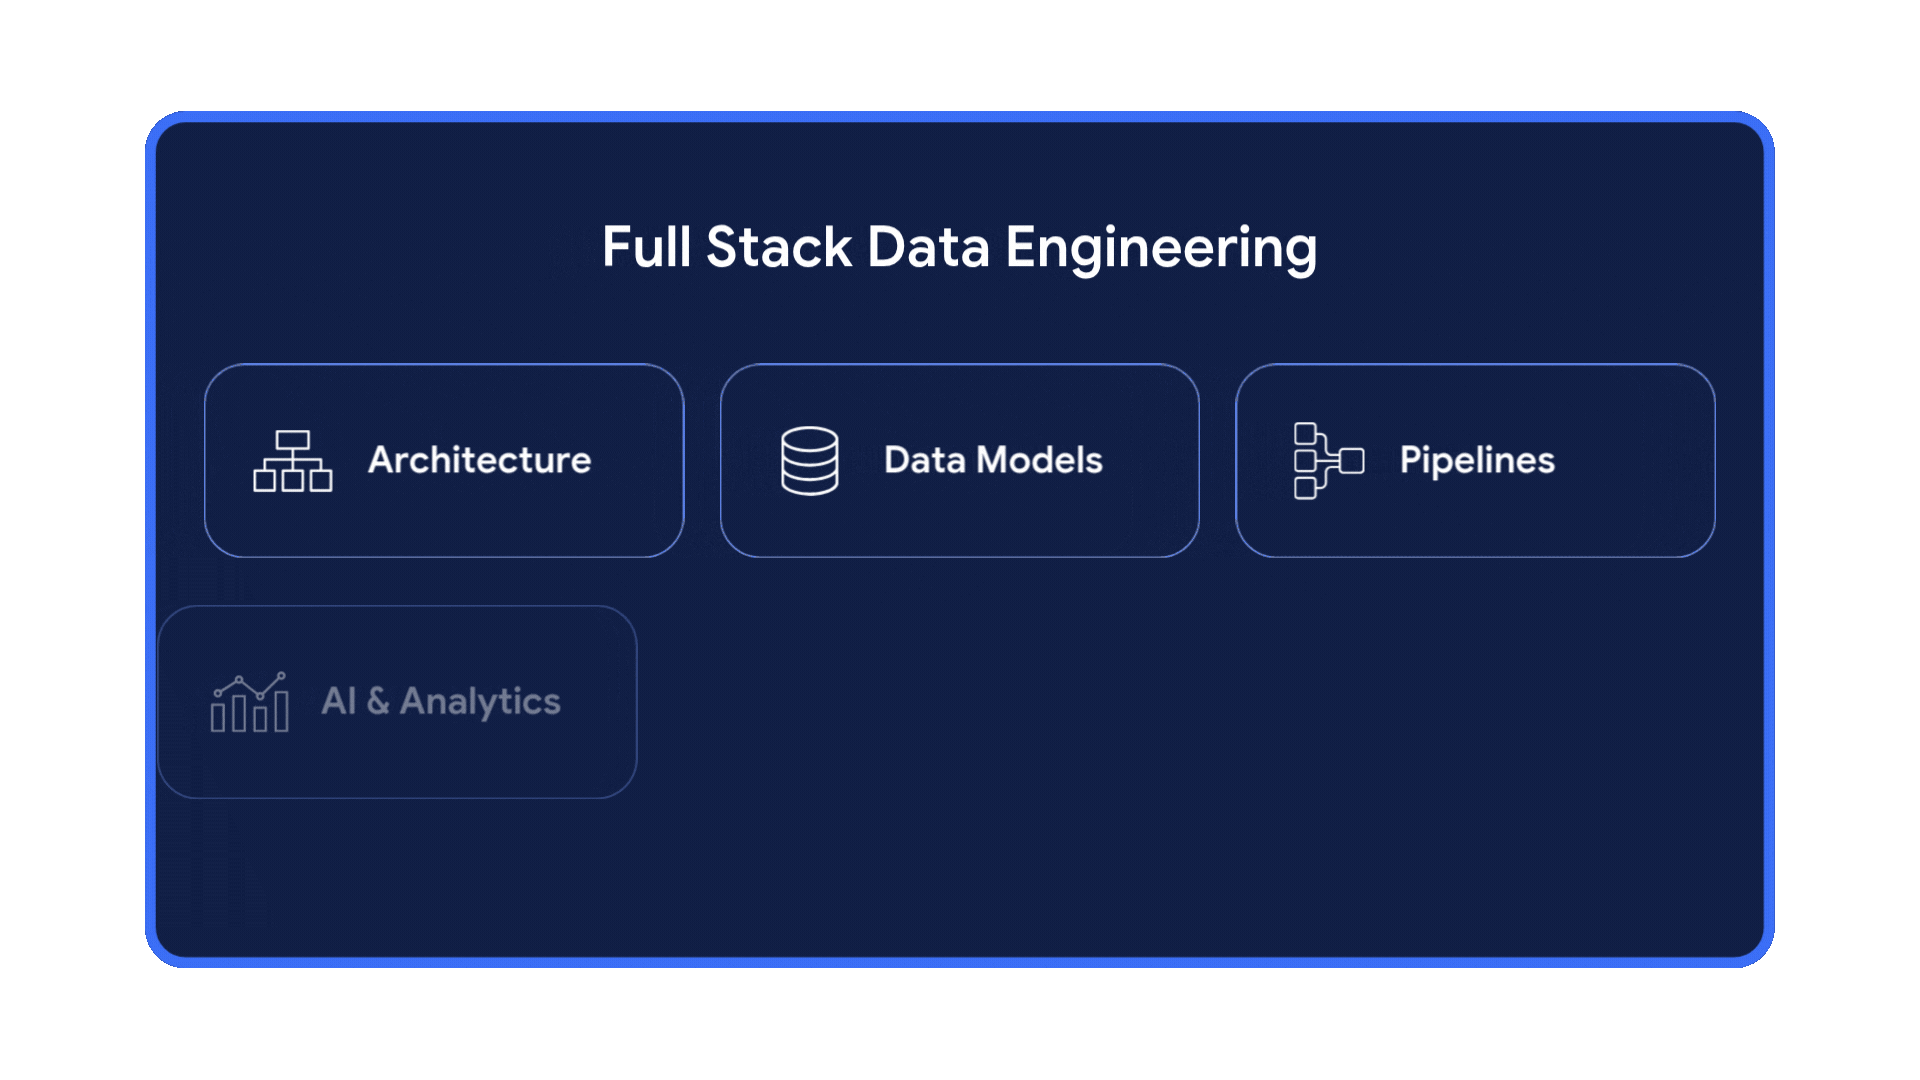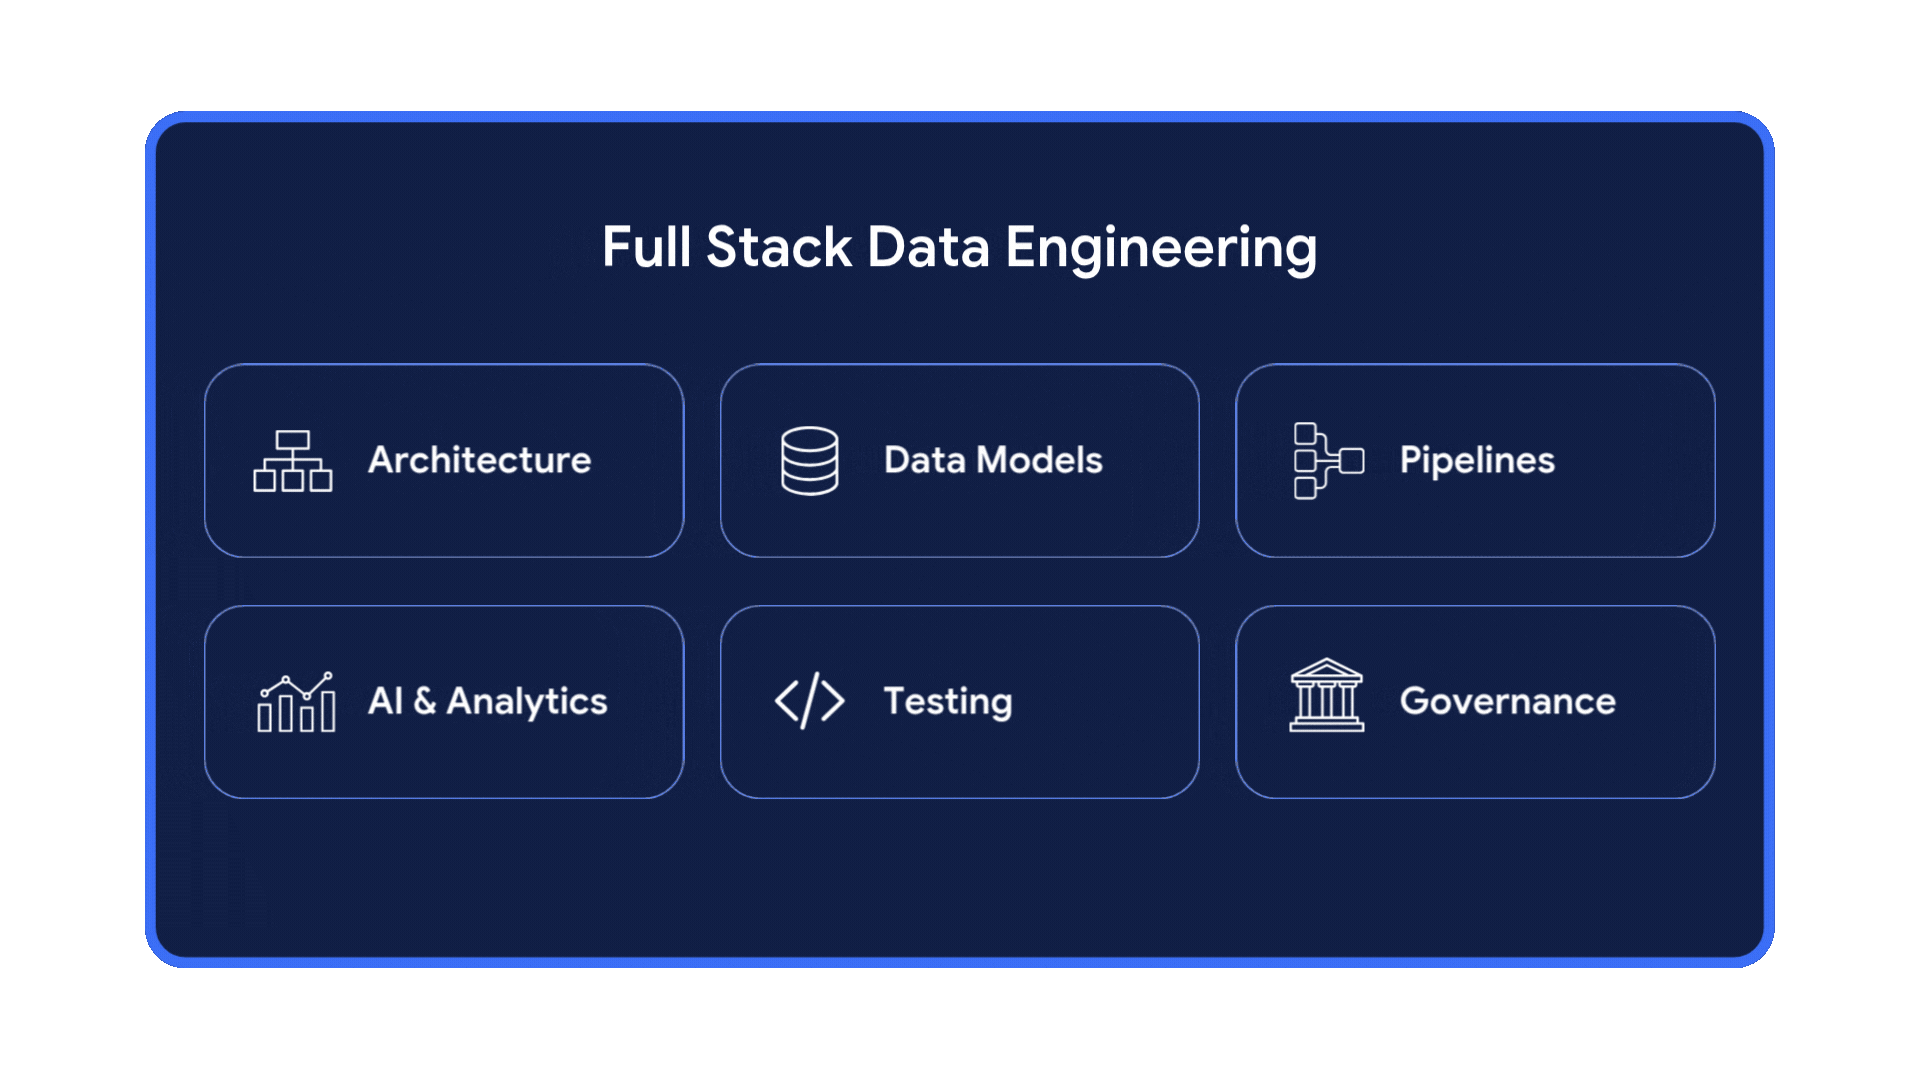
30-50% Faster Cycles
Cut pipeline build and migration timelines by 30-50%
Automated Testing
Pre-built anomaly detection and schema validation
Zero Vendor Lock-in
Deploy across Snowflake, Databricks, dbt, and Cloud VPCs
Manual Data Pipelines & Tech Debt
Teams spend 60%+ of their sprint hours reverse-engineering legacy code, fixing broken schemas, and writing repetitive glue scripts.
 Oracle PL/SQL
 SnowflakeDatabricks
 dbtAirflow
Why Enterprise Data Teams Struggle to Scale
Modern data engineering teams are overwhelmed with repetitive, manual tasks - writing boilerplate transformation scripts, reverse-engineering legacy pipelines, validating data schemas, and migrating between platforms.
Traditional data workflows are slow, error-prone, and heavily reliant on scarce senior engineering talent. When schema drift occurs or source formats change, pipelines break, causing downstream analytical delays and costly remediation efforts.
Data debt accumulates faster than teams can pay it down, pulling high-value engineers away from strategic AI initiatives and forcing them into firefighting operational issues.
GenAI Protos delivers specialized AI-Augmented Data Engineering Accelerators that automate routine pipeline tasks - from intelligent code conversion and automated testing to real-time schema reconciliation and documentation generation - freeing your team to focus on high-impact data initiatives.
How We Accelerate the Data Engineering Lifecycle
GenAI Protos provides modular, AI-powered accelerators designed to automate key stages across the modern data stack.
Assess
Analyze existing data pipelines, identify bottlenecks, and map modernization targets.
Automate
Generate transformation code, schema mappings, and pipeline templates with AI.
Validate
Run automated data quality tests, schema reconciliation, and regression validation.
Deploy
Deploy validated pipelines seamlessly to modern cloud data platforms (Snowflake, Databricks).
Refine
Monitor pipeline health, detect schema drift, and automatically adapt to schema updates.
Engineering Outcomes That Matter
30-50% Faster Development
Cut development cycles for data pipelines, migrations, and schema mappings by 30-50%.
90%+ Accuracy
AI-assisted generation reduces human syntax and logical errors in complex SQL and ETL code.
Reduced Maintenance
Self-healing pipelines and automated drift detection minimize maintenance overhead.
Cost Optimization
Reduce engineering hours spent on repetitive data preparation and pipeline maintenance.
Accelerated Modernization
Migrate from legacy systems to modern cloud data warehouses in weeks instead of months.
Developer Productivity
Empower junior engineers to build production-grade pipelines while freeing senior engineers for strategic work.
Why GenAI Protos Accelerators?
Domain-Trained Code Intelligence
Trained on enterprise data patterns, SQL dialects, and modern ETL frameworks (dbt, Airflow, PySpark).
Platform-Agnostic Design
Works across Snowflake, Databricks, BigQuery, AWS Redshift, and on-premises data warehouses.
Deterministic Guardrails & Testing
Every generated pipeline is validated through automated test suites and schema verification.
Human-in-the-Loop Governance
Full engineer oversight with clear diffs, audit trails, and version-controlled pull requests.
Production-Ready Architecture
Deploy accelerators within your secure VPC, with zero retention of proprietary code or data.
Continuous Enhancement
Accelerators improve over time by learning your enterprise's specific coding standards and patterns.
Our Solutions
Production-ready accelerators that modernize data pipelines and accelerate time-to-value.

AI Powered Data Scripts Converter
Agentic application powered by LLMs that converts thousands of SQL scripts into PySpark DataFrame code with inbuilt validation, accuracy scoring, and actionable feedback.


Fast Data Catalogue
AI-powered platform that automatically discovers, documents, and explains all enterprise data.
Intelligent Data Dictionary
Connects to any database, builds a data dictionary, detects PII, and generates clear business-ready documentation.
AI-Powered Retail Personalisation Platform
Discover how enterprise accelerators modernized recommendation engines with real-time intent graphs and dynamic catalog embeddings, driving measurable conversions across omnichannel retail touchpoints.
Where Our Accelerators Deliver Highest Impact
Automated data dictionary generation, schema drift analysis, and intelligent lineage mapping for enterprise lakes.
Automated legacy script refactoring and SQL query conversion to distributed PySpark workflows with zero manual overhead.
High-speed product catalog indexing, semantic attribute tagging, and recommendation graph generation.
Where These Accelerators Deliver Value
Legacy Database & Data Lake Modernization
Accelerate migrations from legacy databases and data lakes (Teradata, Oracle, Hadoop) to modern cloud platforms.
Data Stack Unification
Standardize ETL logic, dbt models, and orchestration across fragmented enterprise business units.
Automated Data Ingestion
Instantly ingest new third-party APIs, SaaS tools, and partner feeds into analytical data warehouses.
Cross-Team Self-Service
Empower business analysts to generate validated data transformation pipelines without engineering delays.
M&A Data Consolidation
Rapidly reconcile conflicting data models and harmonize schemas during corporate mergers and acquisitions.
Continuous Pipeline Testing
Run automated regression tests across all production data pipelines before deployment.
Frequently Asked Questions
Everything you need to know about our Data Engineering accelerators
What are AI-Augmented Data Accelerators?
How do they integrate with our existing data stack?
Is our proprietary data and code secure?
Can accelerators handle complex, legacy stored procedures?
How much time do these accelerators typically save?
Can non-engineers use these accelerators?
Accelerate Every Stage of Your Data Engineering Journey
Modernize data pipelines, eliminate engineering bottlenecks, and scale your data stack with enterprise-grade AI accelerators tailored to your infrastructure.